Proxy 502 Bad Gateway: Separate Proxy, Upstream, and Destination Failures
A proxy 502 Bad Gateway response means a gateway accepted your request but did not receive a usable response from the next system in the route. The code does not prove that the proxy IP is bad. It can be returned by the proxy service, a reverse proxy at the destination, a CDN, or another intermediary.
Diagnose it in this order: identify the component that generated the 502, preserve the first response and timing, locate the failed upstream stage, compare direct and proxied behavior where authorized, and change one route variable at a time. Repeated rotation before that point can erase the evidence and create a different failure.
Confirm Which Gateway Returned The 502
Save the response status, headers, body signature, timestamp, destination hostname, proxy endpoint, exit IP when known, and request method. A branded error page, a gateway-specific header, or a provider request ID may identify the responding layer. Treat those clues as evidence, not proof, because intermediaries can remove or rewrite headers.
Also record whether the proxy connection and authentication completed. If the client never reached an HTTP response, this is not yet a 502 diagnosis. Use the timeout stage checks when the request only expires, and use the connection reset checks when an established socket closes abruptly.
Map The Route Before Changing It
| Observed stage | What succeeded | Likely next area |
|---|---|---|
| Proxy authentication completed, then immediate 502 | Client-to-proxy connection | Destination scope, upstream DNS, or proxy egress connection |
| HTTP CONNECT succeeded, then 502-like gateway page | Tunnel request reached an intermediary | Destination gateway, CDN, or upstream service |
| 502 after a long delay | Gateway waited for an upstream response | Connect, TLS, first-byte, or upstream processing delay |
| 502 only on one hostname | Proxy works for control destinations | Target-specific DNS, routing, TLS, or destination policy |
| 502 only on one exit | Client and target work through a control route | Exit-specific path or upstream reachability |
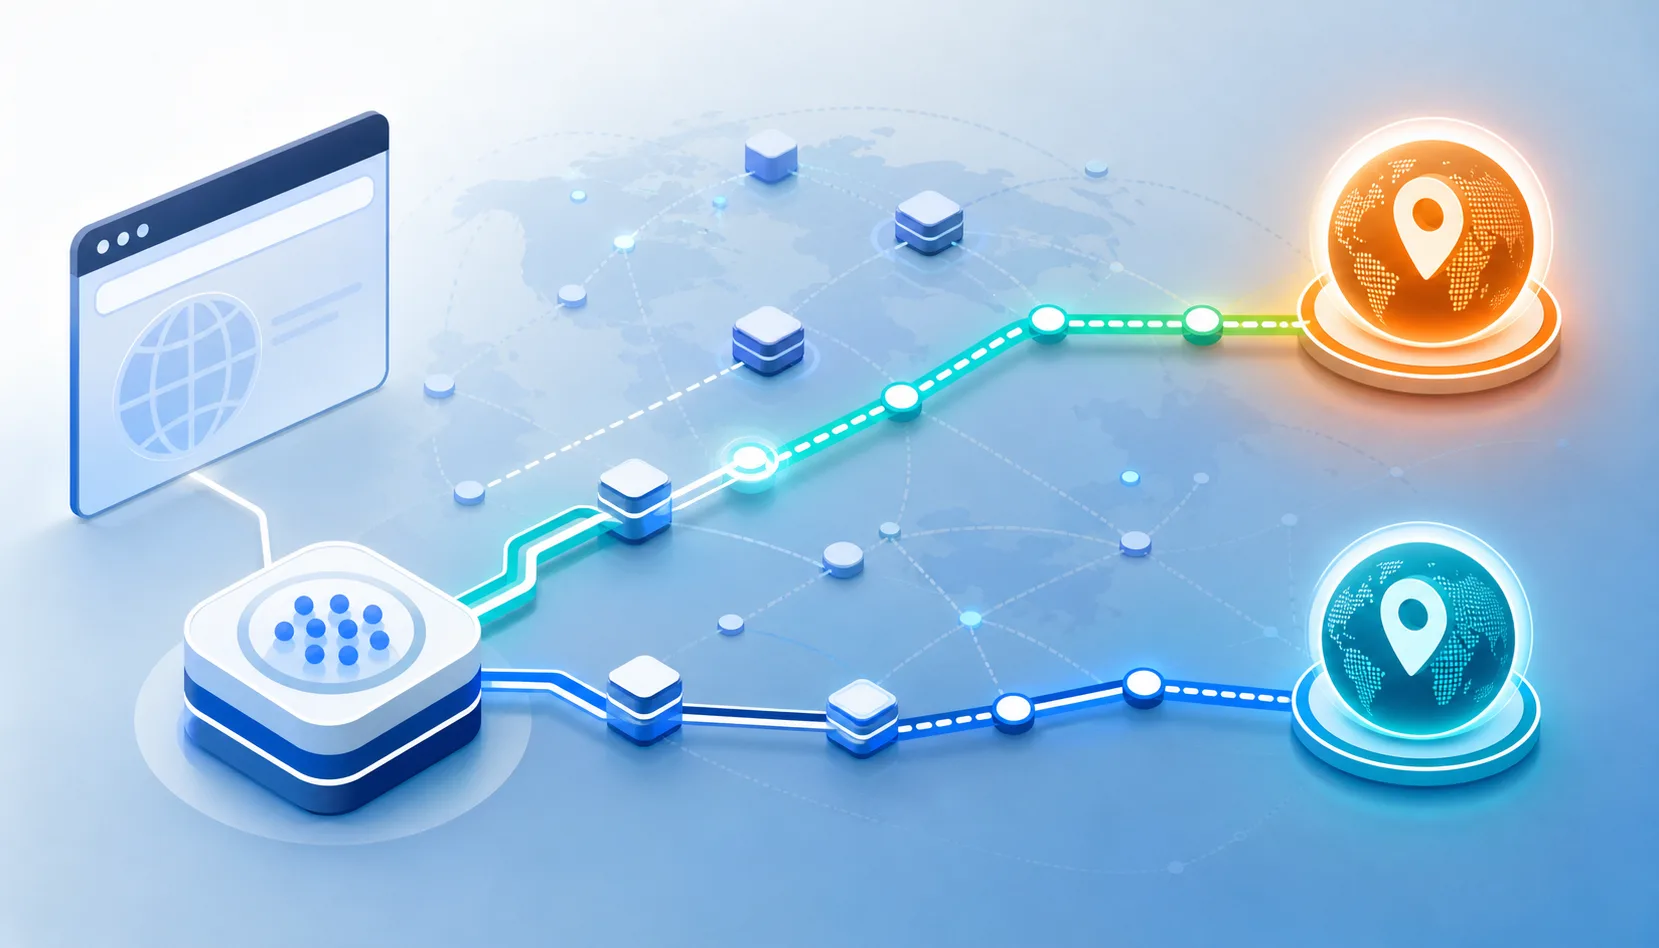
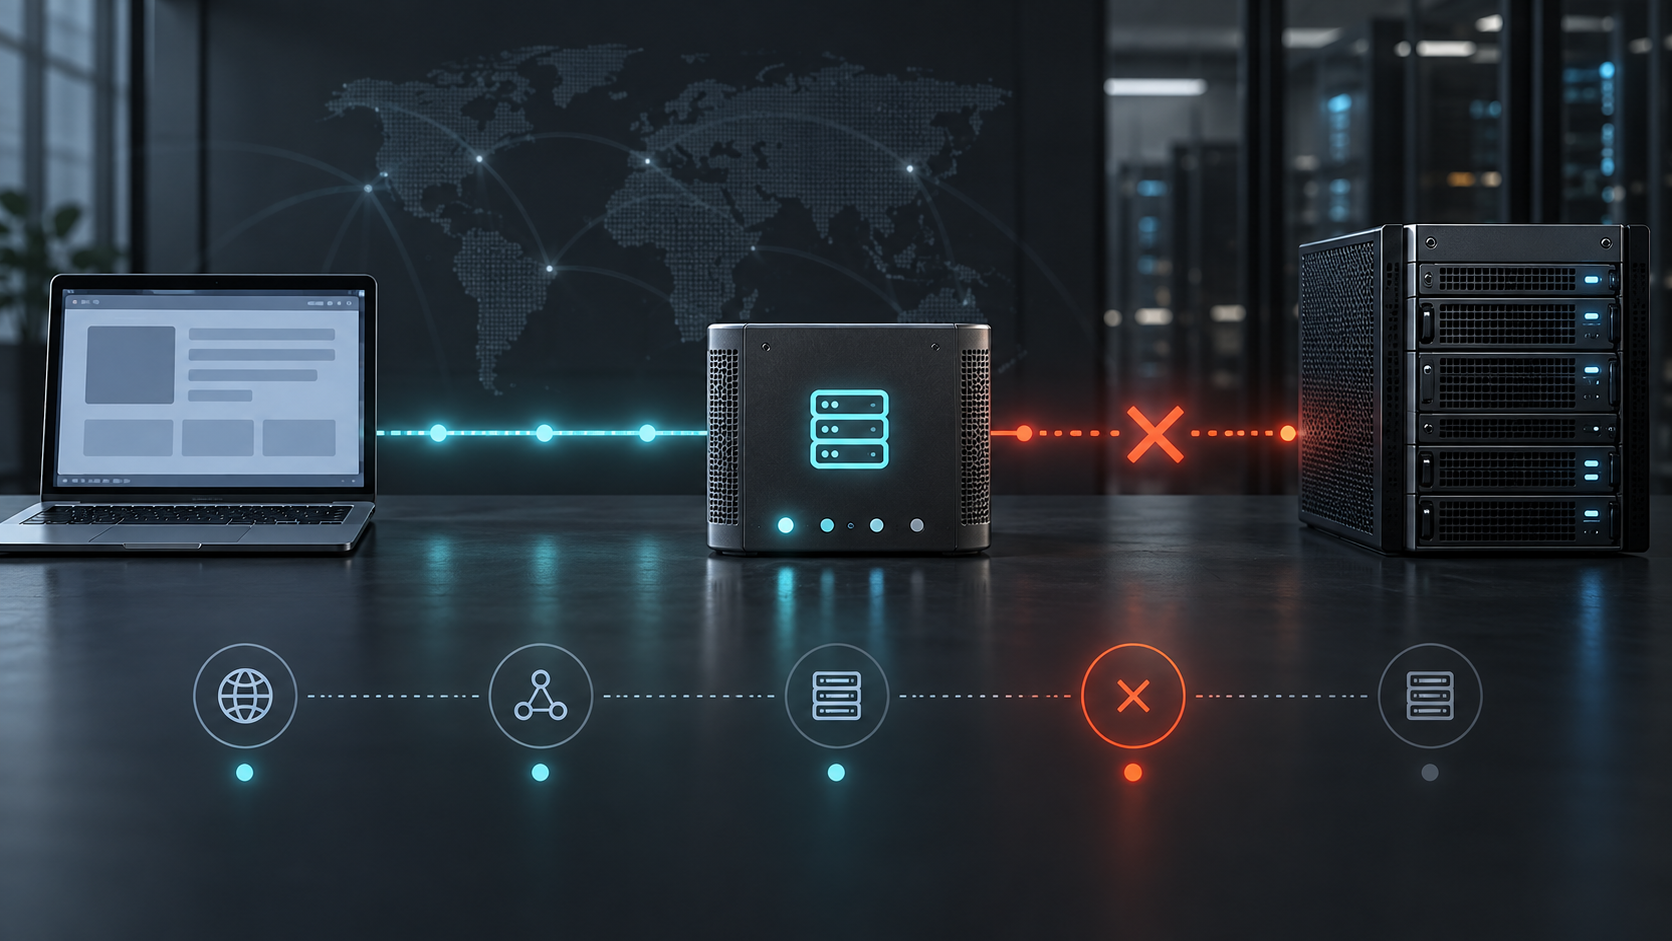
Draw the actual path for this request: client, proxy endpoint, selected exit, DNS resolver, destination edge, and origin service if known. A useful test identifies the last confirmed stage rather than treating every intermediary as one undifferentiated proxy.
Separate DNS, Connect, TLS, And Response Failures
A gateway may translate several upstream failures into the same 502 status. Check whether the upstream hostname resolved, whether a TCP connection opened, whether TLS negotiation completed, and whether response headers arrived. These are different failure layers even when the client sees one code.
If evidence points to encryption setup, follow the TLS handshake diagnostics and preserve SNI, certificate-chain, protocol, and route details. Do not disable certificate verification to make the test pass. A successful insecure test would not establish a safe production fix.
Run One Controlled Comparison
- Choose one low-risk request that consistently returns 502.
- Keep the client, destination hostname, method, headers, payload, and timeout fixed.
- Repeat through the suspected proxy exit and record the full response signature.
- Test one known-good proxy exit with the same request.
- Where authorized, compare a direct request from the same environment.
- Stop after the smallest stable comparison identifies a layer.
Record the route identity, timing stages, response headers, and outcome in the troubleshooting log. If the provider rotates the exit between attempts, stabilize the session first or mark the result ambiguous.
Classify The Result Before Retrying
| Result | Evidence | Next action |
|---|---|---|
| Proxy-gateway-specific | One proxy endpoint returns the same 502 for multiple healthy control targets | Preserve request IDs and escalate with bounded evidence |
| Exit-specific | The same request passes through a control exit but fails through one exit | Quarantine the route and verify replacement behavior once |
| Destination-specific | Control targets pass while one hostname fails across stable exits | Inspect destination DNS, edge, TLS, and upstream availability |
| Request-specific | A small safe request passes but one method or payload consistently fails | Review limits, body handling, and upstream processing |
| Transient | A bounded retry succeeds without route changes and no pattern recurs | Track frequency before changing infrastructure |
| Ambiguous | Route, target, client, or payload changed between attempts | Stop and reduce the test to one variable |
Use Timing To Narrow The Upstream Stage
An immediate 502 often points to policy, resolution, or fast connection rejection. A delayed 502 may indicate an upstream connect deadline, TLS negotiation delay, first-byte timeout, or overloaded destination service. Timing alone is not enough, but consistent timing plus a stable response signature can select the next test.
Add the result to the proxy health scorecard only after route identity is stable. A single destination-specific 502 should not lower every exit’s health score, while repeated cross-target 502 responses on one route deserve quarantine.
Retry Without Creating A Retry Storm
A 502 can be transient, but immediate repeated retries may increase load on an unhealthy upstream and hide which attempt used which route. Use a small retry budget, delay between attempts, and the same route for the first confirmation. Follow the retry policy to decide when to retry, rotate, or stop.
- Retry only idempotent or explicitly safe operations automatically.
- Do not replay an uncertain write without confirming its outcome.
- Record whether a retry reused the connection or opened a new one.
- Do not rotate and change timeout settings in the same test.
Know When To Stop
- Stop if the request could create a duplicate transaction.
- Stop if exits rotate before you can compare like with like.
- Stop if retries trigger rate limits or unrelated policy responses.
- Stop if diagnosis would require disabling TLS verification or another security control.
- Stop if production impact is growing and a low-risk reproduction is unavailable.
- Stop when provider-side or destination-side logs are required to locate the failed upstream.
The Practical 502 Diagnostic Order
First prove that the response is an HTTP 502 and identify the gateway that likely returned it. Next locate the last successful route stage, preserve DNS, connect, TLS, timing, and response evidence, then compare one stable exit and one control path. Classify the result before changing routes or retry policy.
This order keeps a destination outage from being mislabeled as a bad proxy, prevents one unhealthy exit from contaminating the entire pool, and gives operators a compact evidence set for a safe repair or escalation.